Same Model, Different People
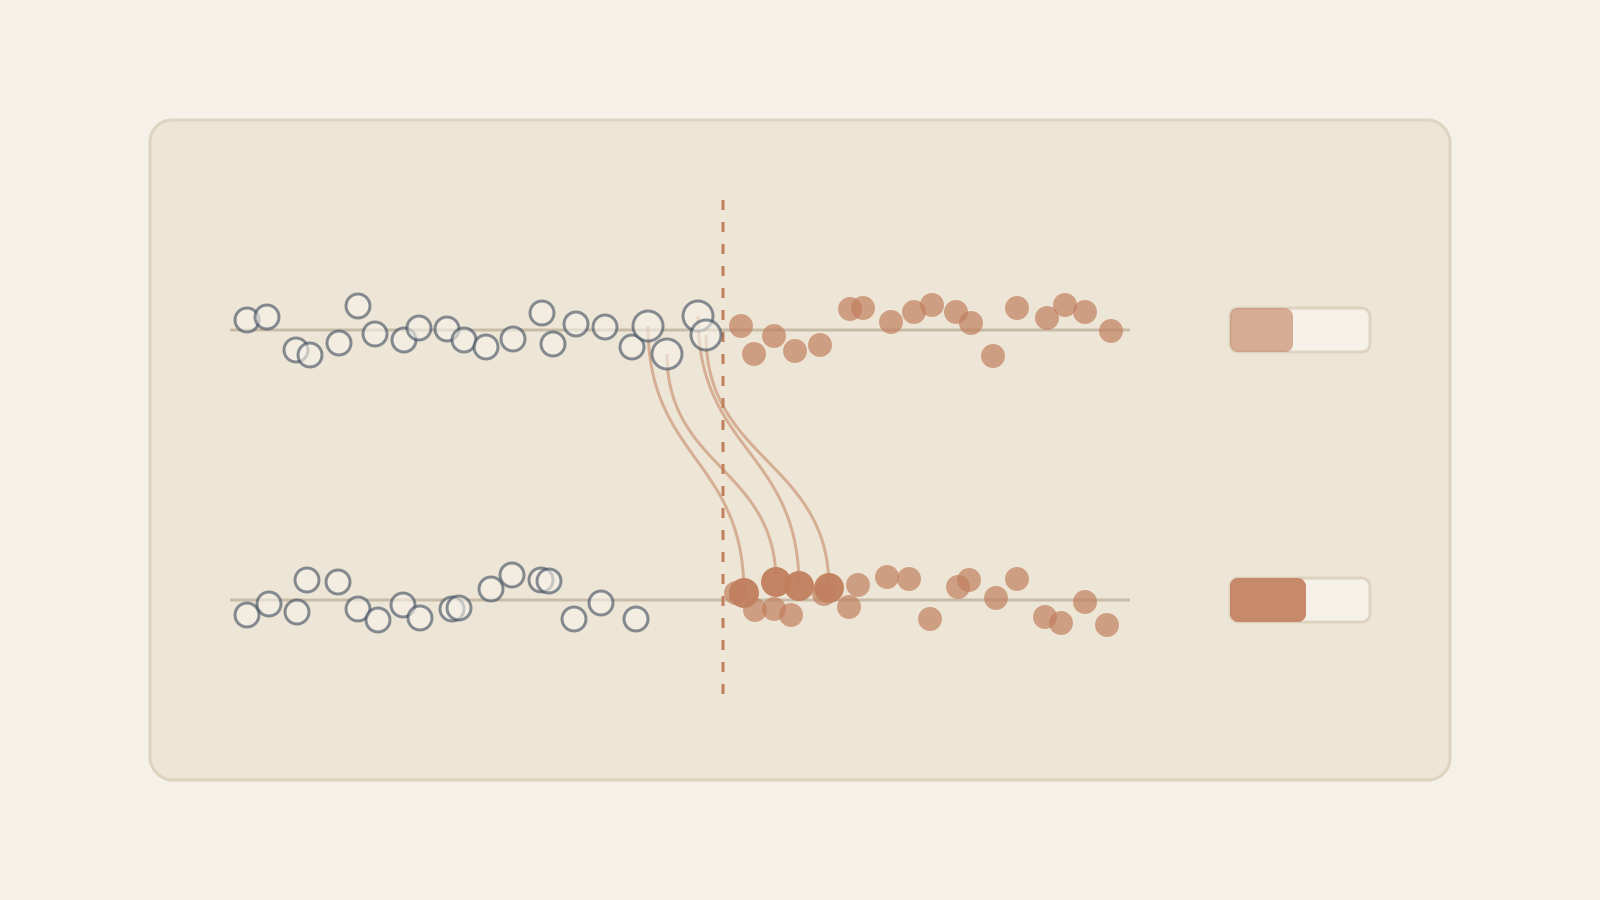
Numerical execution contracts and the reproducibility of fairness audits. The model, the records, the threshold and the audit code stay fixed; only the arithmetic changes, and with it which people a model selects.
Read the PDF 47 pages arXiv: forthcoming
Abstract
Fairness audits treat a trained model as a fixed decision function, but the arithmetic that evaluates it is part of that function. This study holds the model, records, threshold and audit code fixed and varies the numerical execution contract in two tiers. Tier 1 changes only how products and sums are computed, with the serialized weights byte-identical, and is the causal test of arithmetic. Tier 2 runs reduced-precision deployment configurations (BF16 compute, FP8 and 8-bit weights), which can also round weights and change engines and kernels, so its effects belong to the configuration. It audits three tabular model families and two open-weight language models (4B and 24B parameters) on four public tasks, including hospital readmission, on CPUs and GPUs from NVIDIA, AMD and Apple.
Tier 1 changed decisions near the threshold, and which ones depended on the GPU and its software stack, but no verdict under the prespecified, unweighted tests. Tier 2 configurations changed more decisions and some diagnostic verdicts, but no four-fifths verdict. Serving the 24B model with vLLM FP8 selected 54% of people rather than 45% and passed an employment-status audit by sex that its strict FP32 reference failed: its demographic-parity and equalized-odds gaps fell from 0.0567 and 0.0515 to 0.0417 and 0.0394, against a diagnostic tolerance of 0.05. At the reference's selection count FP8 failed demographic parity, and no reading gave its equalized-odds change a paired interval excluding zero. The declared audit depends on the configuration; FP8 is not shown to be fairer.
At the frozen thresholds, every pass-fail verdict a configuration changed had a sampling interval containing its criterion. It proposes an audit stability protocol in which the auditor declares contracts, groups, weights and tests before scoring and records each verdict's range over them apart from its sampling uncertainty.
Authors
Erzheng Zhang, University of Toronto
Agnes Chu, McMaster University
Status
Under review at ACM FAccT 2027. This is the authors' version; an arXiv preprint is forthcoming and will be linked here.
Cite
@unpublished{zhang2026samemodel,
  title  = {Same Model, Different People: Numerical Execution
            Contracts and the Reproducibility of Fairness Audits},
  author = {Zhang, Erzheng and Chu, Agnes},
  year   = {2026},
  note   = {Under review. arXiv: forthcoming},
  url    = {https://erwinzhang.com/research/same-model-different-people/}
}